The fastest way to add AI to a SaaS product is to send a user prompt to a model API and stream the answer back.
It is also the fastest way to discover that a prototype and a product have different trust boundaries.
Enterprise customers will ask which data reached the provider, how tenant isolation is enforced, whether the answer used authorized documents, who can call a write action, how prompts are versioned, what happens during a provider outage, and how usage is allocated to their account. Those are not procurement distractions. They are architecture requirements.
The model is one dependency inside the product. It should not become a parallel application that bypasses identity, authorization, tenancy, audit, and reliability controls the SaaS platform spent years building.
This guide describes how to add LLM and agent capabilities to an existing enterprise SaaS architecture without creating that second, weaker system.
The short answer
Place a controlled AI application layer behind the SaaS product's existing identity and authorization boundary. Route requests through tenant-aware policy, model, retrieval, tool, evaluation, and observability services. Keep business permissions in deterministic code. Give agents narrow tools instead of raw database access. Treat prompts, models, indexes, and policies as versioned production artifacts.
The default request path is:
authenticate the user and tenant; authorize the requested capability; classify data and apply policy; assemble tenant-scoped context; route to an approved model; validate output or proposed tool calls; require approval for consequential actions; execute through existing business services; log the trace, cost, evidence, and outcome.
The common assumption: "We can bolt an LLM onto the
API"
You can, for a demo.
The incomplete part is that LLM applications introduce variable outputs, new data flows, prompt injection, provider dependencies, token-based cost, retrieval infrastructure, evaluation needs, and sometimes model-directed actions. Existing SaaS components still manage customers, roles, records, billing, and business rules. The integration has to preserve those responsibilities.
A useful design principle is: the AI layer may propose; the SaaS domain layer authorizes and executes.
If a customer-support agent proposes a refund, the existing refund service should verify account, policy, limits, permissions, idempotency, and current state. The model should never receive a generic database tool and a prompt that says "follow company policy."
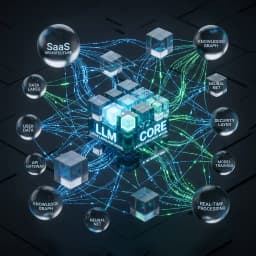
Reference architecture: nine layers
1. Product experience
AI may appear as chat, search, inline generation, a copilot panel, background automation, or an agent task. The interface must show status, sources, limitations, approvals, and failure states. Long-running work needs progress and cancellation, not a frozen chat bubble.
2. Identity, tenant, and entitlements
Reuse the application's identity. Resolve user, organization, role, plan, region, and feature entitlement before context retrieval or model calls.
Do not pass a tenant ID supplied by the client directly into retrieval and assume isolation is solved. Derive tenant scope from authenticated server-side context. Apply row-level and object-level authorization in the data and tool layers.
3. AI policy gateway
The policy gateway decides whether the capability, model, data class, provider, region, and tool are allowed for this request. It can apply PII handling, retention, residency, customer configuration, moderation, rate limits, and approval rules.
This layer prevents policy from being scattered across prompts and endpoints.
4. Model gateway
A model gateway provides a consistent interface across approved providers or self-hosted models. It manages routing, credentials, timeouts, fallbacks, rate limits, token budgets, and telemetry.
Provider abstraction has limits. Model behavior, tool schemas, context limits, and safety features differ. A lowest-common-denominator interface can hide capabilities you need. Abstract operational concerns, but keep model-specific evaluation and adapters explicit.
5. Context and retrieval
The context service assembles system instructions, user state, tenant configuration, approved documents, structured records, and conversation or task history.
RAG should enforce tenant and object permissions before retrieval. Metadata filters, separate indexes, encryption boundaries, or combinations may be appropriate. A vector database does not understand your account model unless you make it.
6. Agent orchestrator
The orchestrator manages goal, state, tools, loop limits, retries, checkpoints, and escalation. Begin with one agent and a small tool set. Multiple agents add coordination, latency, duplicated context, and harder evaluation. Use them when responsibilities and permission boundaries genuinely differ.
7. Business tool layer
Expose narrow domain operations such as get_subscription_status, prepare_case_note, or request_refund_review. Each tool validates identity, tenant, authorization, schema, current record version, and policy.
Write operations should support idempotency. Tool results should be structured and distinguish success, rejection, retryable failure, and unknown outcome.
8. Evaluation and guardrails
Evaluate inputs, retrieval, outputs, and trajectories. Deterministic checks validate formats, citations, permissions, thresholds, and prohibited actions. Model-based graders can help with semantic qualities but should not be the only control for high-impact behavior.
9. Observability and operations
Trace the request across product, retrieval, model, tools, approvals, and business outcome. Capture versions, latency, token usage, cost allocation, errors, and user feedback while respecting privacy and retention requirements.
A detailed request flow
Consider an account administrator asking an embedded support agent: "Why was our invoice higher this month, and correct it if the charge is wrong."
Step 1: authenticate and authorize
The application resolves the administrator's organization and permission to view billing. The AI layer receives a server-issued context, not a user-supplied account ID.
Step 2: separate questions from actions
The request contains an explanation task and a potential correction. The system may allow explanation automatically while requiring an approval workflow for credits or invoice changes.
Step 3: retrieve scoped evidence
The context service fetches invoice lines, plan terms, metered usage, prior credits, and relevant billing policy for this tenant. It does not search a shared document collection without tenant and document filters.
Step 4: generate a grounded explanation
The model produces a structured explanation with references to invoice lines and terms. Deterministic code verifies the cited records exist and belong to the tenant.
Step 5: propose, do not improvise
If a discrepancy appears, the agent calls prepare_billing_case with evidence. The domain service checks duplicate cases, current invoice status, and the user's role.
Step 6: route consequential action
A finance or support owner reviews the proposed credit with the relevant records and policy. Approval is recorded.
Step 7: execute safely
The billing service rechecks record version and authorization, then performs the approved action with an idempotency key.
Step 8: close the loop
The product shows the final status, records the trace, and links the explanation, review, action, and downstream result.
The model helped interpret a messy request. It did not become the billing system.
Multi-tenancy is the non-negotiable boundary
Multi-tenant AI adds leakage paths beyond the primary database:
• retrieval indexes and metadata filters; • conversation and agent memory; • semantic caches; • prompt templates containing tenant configuration; • logs and traces; • evaluation datasets; • tool arguments and results; • background job queues; • file storage and embeddings.
Test isolation at every layer. Include adversarial cases where retrieved content contains another tenant name, a cache key is incomplete, a background job loses context, or a tool attempts to access an object outside scope.
One strong rule: never allow the model to enforce tenant isolation. It can receive tenant-scoped data; it cannot decide what the tenant is allowed to see.
Shared versus isolated infrastructure
Shared models and infrastructure can be safe when logical isolation, encryption, access, logging, and contracts meet requirements. Dedicated indexes, keys, deployments, or accounts may be required for certain customers or regulations. Isolation has cost and operational consequences. Make it a product-tier and risk decision, not an improvised exception.
RAG, memory, and data lifecycle
RAG supplies current, private knowledge at request time. It works only when ingestion and retrieval are treated as production data pipelines.
You need source ownership, connectors, parsing, chunking, metadata, permissions, versioning, deletion, re-indexing, quality checks, and freshness monitoring. If a policy is removed, its chunks must stop appearing. If a user's access changes, cached or remembered content must respect the new authorization.
Conversation memory
Short-term conversation state improves continuity. Long-term memory is more sensitive. Decide what may be remembered, for which user and tenant, for how long, and how it can be corrected or deleted.
Do not store a model-generated summary as unquestioned truth. Keep references to source records and distinguish user-provided facts from inferred preferences.
Semantic caching
Caching can reduce cost and latency, but semantic similarity can return an answer for a different user, permission state, policy version, or tenant if the key is incomplete. Include identity, tenant, entitlement, source version, model/prompt version, and safety-relevant context, or avoid caching sensitive responses.
Agent tools: narrow interfaces, strong contracts
The most dangerous architectural shortcut is giving an agent broad internal access for convenience.
A good tool has:
• one business purpose; • a typed input and output schema; • server-side authorization; • tenant enforcement; • explicit read or write behavior; • business-rule validation; • rate and value limits; • idempotency for writes; • audit events; • predictable errors; • an approval requirement where needed.
Prefer request_plan_change_review over update_any_account_field. Prefer API calls through domain services over direct SQL. The domain layer should remain the source of business truth.
Handle partial failure
An agent may send a message successfully and then time out before receiving confirmation. Retrying blindly can duplicate the action. Tool APIs should return operation IDs and allow status checks. Orchestration should resume from checkpoints rather than replaying the entire trajectory.
Synchronous versus asynchronous execution
Simple generation can stream within a normal web request. Research, multi-tool tasks, and document processing often need asynchronous jobs.
Use a queue and durable state when work may exceed request timeouts, wait for approvals, or survive deployment. The UI should show queued, running, waiting for review, completed, failed, and canceled states.
Design cancellation carefully. Canceling the model call does not undo an external action already completed.
Reliability and provider failure
LLM providers have rate limits, regional availability, model deprecations, and behavior changes. A fallback model may preserve uptime while reducing quality or changing compliance conditions.
Define which features can degrade:
• fall back to a smaller approved model; • switch to search-only results; • return a structured manual-work item; • pause write actions; • disable the feature through a flag; • queue the task for later.
Test these modes. A circuit breaker that no one has seen until an incident is documentation, not resilience.
Security threat model
Prompt injection
Users and retrieved documents may contain instructions that attempt to override policy or exfiltrate data. Treat external text as untrusted. Separate system instructions, restrict tools, validate arguments, and test indirect injection.
Excessive permissions
Use user-delegated or tightly scoped service credentials. Do not share one powerful integration credential across tenants and rely on prompt wording.
Sensitive-data exposure
Classify data before model calls. Minimize fields, redact where appropriate, encrypt in transit and at rest, control logs, and verify provider handling, retention, residency, and contract terms.
Insecure output handling
Generated HTML, code, URLs, queries, and tool arguments are untrusted output. Escape, validate, sandbox, and enforce policy before use.
Supply-chain and model change
Track provider, model version, SDKs, orchestration libraries, prompts, and tools. Re-run evaluations after material changes. Keep rollback paths.
Evaluation before and after launch
Create a versioned evaluation set from representative tenant and role scenarios. Include:
• normal questions with known evidence; • missing and conflicting records; • objects outside the user's permission; • cross-tenant lookalikes; • stale documents; • prompt-injection content; • tool errors and timeouts; • duplicated requests; • actions requiring approval; • provider failure and fallback.
Score answer support, retrieval recall, citation correctness, authorization, tool selection, tool arguments, escalation, latency, and cost. For agent features, evaluate the trajectory, not only the final message.
After launch, connect quality signals to product outcomes: task completion, support reopens, user correction, approval rate, incident rate, cost per tenant, and retention or adoption where appropriate.
Observability without creating a privacy problem
Useful traces include request ID, tenant, user role, feature, model, prompt/policy version, retrieved source IDs, tool calls, approval, latency, token use, and outcome.
Do not log every raw prompt and document indefinitely. Apply data minimization, field-level redaction, access control, retention, and regional requirements. Security teams need visibility; customers need privacy. The design must support both.
Cost controls for a multi-tenant product
Token cost is variable and user-driven. Add:
• per-user and per-tenant quotas; • maximum input, output, and loop budgets; • model routing by task; • retrieval limits; • rate limiting and concurrency controls; • cost attribution by feature and customer; • anomaly alerts; • graceful limit messages; • plan-aware entitlements.
Measure cost per completed product task. A cheap call that leads to three retries and a support ticket is not cheap.
Be careful with unlimited plans. A few automated customers or agent-to-agent integrations can produce machine-speed usage that human assumptions never modeled.
Rollout framework for an existing SaaS product
Phase 1: assistive, read-only feature
Start with search, summarization, or drafting for internal users or a small customer cohort. No write tools. Establish traces and evaluation.
Phase 2: tenant-aware retrieval
Connect approved data with permission enforcement, citations, deletion, and freshness monitoring. Test isolation aggressively.
Phase 3: prepared actions
Allow the agent to prepare a domain action. A user reviews and executes it through the existing product workflow.
Phase 4: bounded tool execution
Automate low-risk reversible actions with limits, idempotency, and monitoring. Keep higher-impact actions approval-gated.
Phase 5: scaled operations
Add provider routing, asynchronous jobs, customer controls, cost allocation, incident runbooks, and regular regression evaluation.
This staged approach is not slow. It prevents the team from learning about identity, tenancy, and recovery after write access is already live.
Build, buy, and platform choices
Managed model APIs reduce infrastructure work. Self-hosted or dedicated models can offer control but add capacity, security, upgrade, and performance responsibility. Workflow platforms accelerate internal automation. Custom application code is usually required where tenant-aware product behavior, deep domain services, and user experience are central.
Choose components by data boundary, latency, quality, operating skill, portability, and total cost. Avoid platform decisions before defining the request flow and failure modes.
Custom does not mean building every layer. A good architecture uses managed capabilities where they fit and keeps differentiating policy, domain logic, and product experience under your control.
Common implementation mistakes
Building a separate AI permission model
Reuse product identity and authorization. Parallel permission systems drift.
Filtering tenants only in the prompt
Enforce scope in retrieval, cache, memory, tools, and data queries.
Letting agents call internal services with admin credentials
Use narrow, tenant-aware operations and least privilege.
Logging sensitive context by default
Design observability with minimization and retention from the beginning.
Treating fallback models as equivalent
Evaluate each approved model and define which features may use it.
Shipping chat before defining value
Tie the feature to a product task and measurable outcome. A blank chat box often creates discovery work for users rather than removing it.
Ignoring model and prompt versioning
Without versions, regression investigation becomes guesswork.
Frequently asked questions
What is enterprise LLM architecture?
It is the application, data, security, and operations design that lets an organization use large language models reliably. It includes identity, policy, model routing, context, retrieval, tools, evaluation, observability, cost, and human controls.
Where should an LLM sit in a SaaS architecture?
Behind the application's authenticated server boundary, accessed through controlled services that enforce tenant, data, model, and tool policy.
How do you prevent cross-tenant leakage in RAG?
Derive tenant scope from authenticated context, enforce metadata and object permissions before retrieval, isolate infrastructure where required, secure caches and memory, and test every layer with adversarial cases.
Should AI agents have direct database access?
Usually no. Expose narrow domain tools that enforce authorization, business rules, tenancy, limits, and audit events.
Do we need a model gateway?
It becomes valuable when several features, models, providers, regions, or teams need consistent routing, credentials, budgets, observability, and policy. A small product can begin with a thin internal adapter.
How should prompts be managed?
Treat system prompts and policies as versioned artifacts with owners, reviews, tests, rollout, and rollback. Do not bury critical business rules only in prompts.
How is an AI agent different from an AI feature?
A generative feature produces an output. An agent can select tools and pursue a multi-step goal. Agentic execution requires stronger state, permissions, validation, recovery, and trajectory evaluation.
What should be logged?
Log identifiers and versioned traces needed for quality, security, billing, and support, while minimizing or redacting raw sensitive content and enforcing retention and access.
How do you control LLM cost in SaaS?
Use quotas, budgets, routing, context limits, loop limits, caching with safe keys, rate limits, and per-tenant cost attribution. Optimize for completed task cost.
How should an AI feature be rolled out?
Begin with read-only assistive use, then tenant-aware retrieval, prepared actions, bounded execution, and scaled operations. Use feature flags, cohort releases, evaluation gates, and rollback.
Conclusion
The architecture around the LLM determines whether AI becomes a dependable product capability or an expensive exception to the platform's rules.
Preserve the SaaS trust boundary. Authenticate first. Enforce tenancy before retrieval. Keep authorization and business policy in code. Give agents narrow tools. Trace the full request. Design for provider failure, variable cost, and model change. Expand from assistive output to action only when evaluation and recovery support it.
The goal is not to make the model the center of the system. The goal is to make AI useful inside a system customers already trust.
Actionable next steps
Draw one AI request from user to model, data, tool, and final outcome. Mark identity, tenant, authorization, data class, and audit boundaries. List every new store: prompts, indexes, memory, caches, traces, and evaluation data. Replace broad internal access with narrow domain tools. Build isolation, injection, timeout, duplicate, and approval cases into the evaluation set. Define per-tenant cost and rate controls before public release. Ship to a small cohort with a read-only or prepare-only capability and a rollback plan.
Wizora Studio supports AI solutions for SaaS companies, custom AI development, and AI agent development. A practical architecture review should begin with one request flow and its trust boundaries, not a list of model features.
References and editorial evidence
• Wizora Studio - current page at the supplied architecture URL • AWS - Generative AI Lens, Well-Architected Framework • Google Cloud - Choose Agentic AI Architecture Components • Google Cloud - Multi-Tenant Agentic AI System • NIST - Secure Software Development Practices for Generative AI • NIST - AI Risk Management Framework
Editorial note: the billing-assistant flow is a composite architecture scenario, not a claimed client case study. Architecture and regulatory requirements must be validated for each product, provider, customer contract, and jurisdiction.
AI Model Fine-Tuning: a practical decision framework
AI Model Fine-Tuning should be evaluated against the real problem, the intended audience, the systems involved, and the level of human review required. The right approach is the one that makes the workflow more useful and more inspectable, not the one that simply adds another tool or trend to the stack.
Key topics to cover
- AI Model Fine-Tuning guide
- AI Model Fine-Tuning explained
- AI Model Fine-Tuning best practices
- AI Model Fine-Tuning examples
Use these topics as supporting language only when they answer a real question in the article. Explain the implementation choices in plain language, distinguish a reliable workflow from a prototype, and qualify claims that depend on the project scope, data quality, vendor limits, or operating model.
Questions readers should ask
- How does AI Model Fine-Tuning work?
- What is AI Model Fine-Tuning?
- What are best practices for AI Model Fine-Tuning?
Limits, evidence, and next steps
Results depend on the workflow, inputs, integrations, security requirements, and review process. Do not treat this guide as a guarantee of cost, speed, rankings, compliance, or business outcomes. Document the assumptions, define what will be measured, and keep a clear stopping or escalation condition.
If you want to map the topic to a real project, review the relevant Wizora service or contact Wizora Studio with the current process, constraints, and desired outcome.
Integrate LLMs and AI Agents Into Enterprise SaaS: a practical decision framework
Integrate LLMs and AI Agents Into Enterprise SaaS should be evaluated against the real problem, the intended audience, the systems involved, and the level of human review required. The right approach is the one that makes the workflow more useful and more inspectable, not the one that simply adds another tool or trend to the stack.
Key topics to cover
- Integrate LLMs and AI Agents Into Enterprise SaaS architecture
- Integrate LLMs and AI Agents Into Enterprise SaaS best practices
- Integrate LLMs and AI Agents Into Enterprise SaaS examples
- Integrate LLMs and AI Agents Into Enterprise SaaS implementation
Use these topics as supporting language only when they answer a real question in the article. Explain the implementation choices in plain language, distinguish a reliable workflow from a prototype, and qualify claims that depend on the project scope, data quality, vendor limits, or operating model.
Questions readers should ask
- how Integrate LLMs and AI Agents Into Enterprise SaaS works
- how to use Integrate LLMs and AI Agents Into Enterprise SaaS
- The short answer
Limits, evidence, and next steps
Results depend on the workflow, inputs, integrations, security requirements, and review process. Do not treat this guide as a guarantee of cost, speed, rankings, compliance, or business outcomes. Document the assumptions, define what will be measured, and keep a clear stopping or escalation condition.
If you want to map the topic to a real project, review the relevant Wizora service or contact Wizora Studio with the current process, constraints, and desired outcome.